AI Glossary
LLM Embeddings – Short Explanation
LLM embeddings are numerical representations of text, images, audio, or other data that help large language models and AI systems understand meaning, similarity, and relationships between different pieces of information.
Instead of treating words or data as isolated items, embeddings convert them into vectors that capture semantic meaning. A vector is simply a list of numbers. This allows AI systems to recognize that two phrases can be related even when they do not use the same exact words.
For example, an LLM embedding can help an AI system understand that “customer support issue,” “help desk request,” and “service complaint” may be semantically connected. This makes embeddings essential for semantic search, retrieval-augmented generation, recommendation systems, clustering, classification, and many enterprise AI applications.
LLM embeddings are often also referred to as vector embeddings, text embeddings, or embedding vectors.
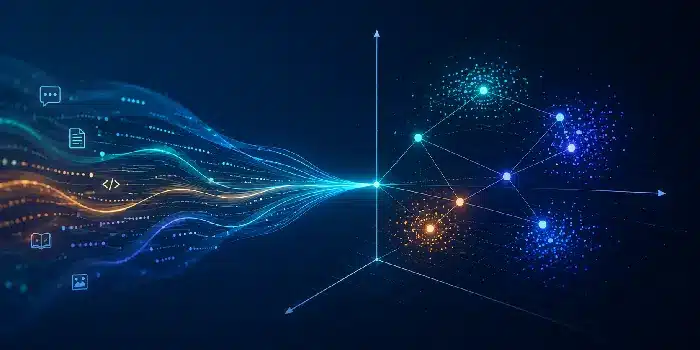
Table of Contents
- How LLM embeddings work
- Why LLM embeddings are important
- LLM embeddings and vector databases
- LLM embeddings and retrieval-augmented generation
- Use cases of LLM embeddings
- Benefits of LLM embeddings
- Challenges of LLM embeddings
- LLM embeddings in business
- LLM embeddings and multimodal AI
- The future of LLM embeddings
- FAQs about LLM embeddings
How LLM embeddings work
LLM embeddings work by converting data into mathematical vectors. Each vector represents the meaning or characteristics of the original input in a way that a machine learning model can process.
In natural language processing, an embedding model analyzes text and maps it into a high-dimensional vector space. Words, sentences, documents, or queries with similar meanings are placed closer together in that space. This allows AI systems to compare information based on meaning rather than only matching keywords.
For example:
- “How do I reset my password?”
- “I forgot my login credentials.”
- “Help me access my account.”
These phrases use different wording, but an embedding model can recognize that they are related because they share similar intent.
This is why embeddings are a key component of modern AI systems that need to retrieve, classify, compare, or organize large amounts of unstructured data.
Why LLM embeddings are important
LLM embeddings are important because they make it possible for AI systems to work with meaning, not just exact words.
Traditional keyword-based systems often depend on literal matches. If a user searches for “affordable running shoes,” a keyword search may miss content that uses phrases like “budget-friendly sneakers” or “low-cost athletic footwear.” Embeddings help solve this problem by identifying semantic similarity.
This makes LLM embeddings especially valuable for applications such as semantic search, enterprise knowledge retrieval, customer support automation, recommendation engines, document classification, duplicate detection, clustering and topic analysis, and retrieval-augmented generation.
For businesses, embeddings help AI systems find more relevant information, improve user experiences, and make large volumes of unstructured data easier to use.
LLM embeddings and vector databases
LLM embeddings are often stored in vector databases. A vector database is designed to store, index, and search embedding vectors efficiently.
When a user submits a query, the query is also converted into an embedding. The system then compares that query embedding against stored embeddings to find the most semantically similar content. This process is known as vector search or similarity search.
For example, a company might convert thousands of support articles, product descriptions, or internal documents into embeddings and store them in a vector database. When a user asks a question, the system retrieves the most relevant documents based on semantic similarity.
Vector databases are an important part of many modern LLM applications because they allow AI systems to search large knowledge bases quickly and contextually.
Tip: Build better LLM embeddings with high-quality data from LXT
LLM embeddings are only effective when the underlying data is accurate, relevant, and representative of real-world use cases.
At LXT, we provide high-quality data collection, annotation, search relevance evaluation, and LLM evaluation services to help organizations build and improve AI systems that rely on embeddings, semantic search, and retrieval-augmented generation.
LLM embeddings and retrieval-augmented generation
LLM embeddings are a core component of retrieval-augmented generation, also known as RAG.
In a RAG system, embeddings are used to retrieve relevant information from an external knowledge source before a large language model generates an answer. This helps the model respond with information that is more grounded, specific, and relevant to the user’s question.
A typical RAG workflow includes:
- Documents are converted into embeddings.
- The embeddings are stored in a vector database.
- A user query is converted into an embedding.
- The system retrieves the most relevant documents or passages.
- The LLM uses that retrieved context to generate a response.
This approach is especially useful for enterprise AI applications where the model needs access to company-specific knowledge, product documentation, policy documents, support content, or frequently updated information.
Use cases of LLM embeddings
LLM embeddings power a wide range of AI applications across consumer and enterprise use cases:
| Use Case | Description |
|---|---|
| Semantic search | Embeddings help search systems understand the meaning behind a query instead of relying only on exact keyword matches. This improves search relevance for websites, ecommerce platforms, enterprise knowledge bases, and support portals. |
| Retrieval-augmented generation | Embeddings allow RAG systems to retrieve relevant documents, passages, or knowledge snippets before an LLM generates an answer. |
| Recommendation systems | Embeddings can help identify similar products, articles, videos, or user preferences, making recommendations more personalized and context-aware. |
| Text classification | Embeddings can be used to classify text into categories such as topic, intent, sentiment, risk level, or customer request type. |
| Clustering and topic discovery | Businesses can use embeddings to group large volumes of text into related themes. This is useful for analyzing surveys, reviews, support tickets, social media posts, and open-ended feedback. |
| Duplicate and near-duplicate detection | Embeddings can identify content that is semantically similar, even when the wording is different. This helps detect duplicate documents, repeated user questions, or similar claims. |
| Multilingual search | Embeddings can support cross-lingual similarity, helping systems match related content across languages when the embedding model is trained for multilingual use cases. |
Benefits of LLM embeddings
When integrated into AI workflows, embeddings turn unstructured data into structured, machine-readable input. Here are the key benefits:
| Benefit | Explanation |
|---|---|
| Better search relevance | Embeddings improve search by matching meaning rather than relying only on keywords. Users find relevant results even when they phrase queries differently from the source content. |
| Improved user experience | When AI systems understand intent and context more effectively, users receive better answers, recommendations, and search results. |
| More effective use of unstructured data | Most business data is unstructured, including emails, documents, call transcripts, survey responses, product reviews, images, and videos. Embeddings make this data easier to organize, search, and analyze. |
| Stronger RAG performance | High-quality embeddings can improve the relevance of retrieved context in RAG systems, leading to more accurate and useful LLM-generated responses. |
| Scalable knowledge retrieval | Embeddings allow organizations to search and compare large volumes of information efficiently, making them useful for enterprise AI systems. |
Challenges of LLM embeddings
Despite their power, working with embeddings comes with practical challenges:
| Challenge | Why It Matters |
|---|---|
| Data quality | Embeddings are only as useful as the data they represent. Incomplete, outdated, biased, or poorly structured data can reduce the quality of search, classification, and retrieval results. |
| Model selection | Different embedding models perform better for different tasks. A model that works well for short search queries may not be ideal for long documents, multilingual content, or multimodal data. |
| Evaluation | Embedding-based systems need to be evaluated carefully. Businesses must test whether retrieved results are actually relevant, accurate, and useful for end users. |
| Bias and representation | If the training data or source data contains bias, embeddings may reflect or amplify those patterns. This makes human review and responsible AI practices important. |
| Cost and scalability | Generating, storing, and searching embeddings at scale can require significant infrastructure, especially for large enterprise datasets. |
LLM embeddings in business
LLM embeddings are increasingly important for businesses that want to use AI with their own data.
In customer support, embeddings can help match customer questions with the most relevant help center articles or previous support cases. In ecommerce, they can improve product search and recommendations. In market research, embeddings can help group open-ended survey responses into meaningful themes. In enterprise knowledge management, they can help employees find relevant internal documents more quickly.
Common business applications include:
- Improving website and app search
- Powering AI assistants and chatbots
- Organizing customer feedback
- Analyzing support tickets
- Matching users with relevant content
- Detecting similar documents or claims
- Supporting RAG-based enterprise AI tools
For companies building AI systems, embeddings are often one of the most important building blocks for connecting large language models with real-world business data.
LLM embeddings and multimodal AI
LLM embeddings are not limited to text. Modern AI systems can also create embeddings for images, audio, video, and other data types.
In multimodal AI, embeddings can help connect different forms of data in a shared representation space. For example, a system may learn that an image of a running shoe, a product description, and a spoken query about athletic footwear are all related.
This is especially important as AI applications increasingly combine text, speech, image, and video inputs. Multimodal embeddings can support applications such as visual search, voice search, content moderation, product discovery, and AI training data analysis.
The future of LLM embeddings
The future of LLM embeddings is closely connected to the growth of generative AI, multimodal AI, and enterprise AI systems.
As more organizations adopt LLM-powered tools, embeddings will play an increasingly important role in connecting models to proprietary knowledge, improving search relevance, personalizing user experiences, and enabling more accurate retrieval.
Future embedding models are likely to become more powerful across languages, modalities, and specialized domains. Businesses will also place greater emphasis on evaluating embedding quality, reducing bias, improving data governance, and ensuring that AI systems retrieve the right information at the right time.
FAQs about LLM embeddings
LLM embeddings are numerical representations that capture the meaning of text, images, audio, or other data. They take the form of vectors, which are lists of numbers, and allow AI systems to compare information based on meaning rather than just matching exact words.
Tokens are the small units of text (words or word parts) that an LLM processes. Embeddings are the numerical vectors that represent those tokens or longer pieces of content in a way that captures their meaning. Learn more about tokenization in LLMs.
RAG systems use embeddings to find the most relevant documents or passages before the LLM generates an answer. Better embeddings lead to more relevant retrieved context, which in turn improves the accuracy and usefulness of the model’s response.
Yes. Multilingual embedding models map text from different languages into a shared vector space, so a query in one language can retrieve relevant content in another. The quality depends on how well the model was trained on diverse multilingual data.
Embeddings are only as good as the data behind them. High-quality training data should be accurate, relevant to the target use case, representative of real-world inputs, and free of avoidable bias. Professional data collection and annotation services help ensure these standards are met.