AI Glossary
Retrieval-Augmented Generation – Short Explanation
Retrieval-Augmented Generation, often shortened to RAG, is an AI framework that connects a large language model with external knowledge sources before generating an answer.
Instead of relying only on the information contained in the model’s training data, a RAG system retrieves relevant information from documents, databases, websites, knowledge bases, or other data sources. The large language model then uses this retrieved context to generate a more accurate, relevant, and grounded response.
RAG is especially important for enterprise AI applications because it allows organizations to use large language models with their own company-specific data. This can include product documentation, customer support articles, internal policies, research reports, technical manuals, legal documents, or frequently updated information.
By combining information retrieval with generative AI, RAG helps AI systems produce answers that are more context-aware, up to date, and useful for real-world business needs.
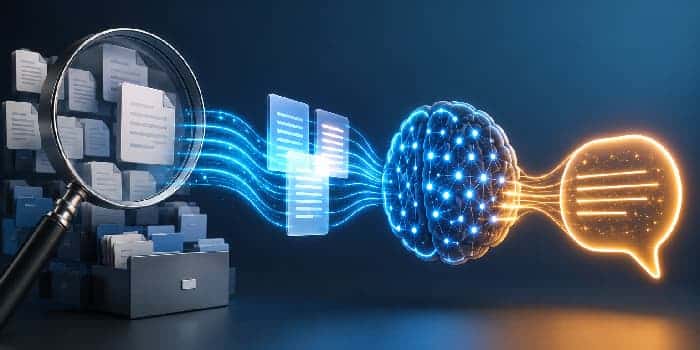
Table of Contents
How Retrieval-Augmented Generation works
A RAG system typically works in two main steps: retrieval and generation.
During the retrieval step, the system searches an external knowledge source for information that is relevant to the user’s query. This information may come from a knowledge base, document repository, vector database, website, or enterprise data system.
During the generation step, the large language model uses the retrieved information as context to generate a response.
A typical RAG workflow includes:
- Business documents or data are collected and prepared.
- The content is split into smaller sections or passages.
- These sections are converted into embeddings.
- The embeddings are stored in a vector database or search index.
- A user asks a question.
- The user query is converted into an embedding or used in a search process.
- The system retrieves the most relevant information.
- The large language model generates an answer based on the retrieved context.
This process allows the model to answer questions using information that may not have been part of its original training data.
Why RAG is important
RAG is important because large language models have limitations.
LLMs are powerful, but they do not automatically know an organization’s private data, newly updated information, or highly specific domain knowledge. They may also generate answers that sound confident but are incorrect or unsupported. This is often referred to as hallucination.
RAG helps address these limitations by giving the model access to relevant external information at the time of the query. Instead of asking the model to rely only on its internal knowledge, a RAG system provides supporting context from selected sources.
This makes RAG valuable for applications where accuracy, traceability, and relevance are important.
For example, a customer support chatbot using RAG can retrieve the latest help center article before answering a customer question. An internal AI assistant can search company policies before responding to an employee. A research tool can retrieve relevant documents before summarizing findings.
Tip: Build better RAG systems with high-quality data from LXT
RAG systems depend on high-quality data, relevant retrieval, and careful evaluation.
At LXT, we provide data collection, annotation, search relevance evaluation, LLM evaluation, and human feedback services to help organizations build and improve AI systems that rely on retrieval-augmented generation. By combining high-quality data with human evaluation, businesses can improve the relevance, accuracy, and reliability of RAG-powered AI applications.
RAG and large language models
Retrieval-Augmented Generation is closely connected to large language models.
An LLM generates the final response, but the quality of that response depends heavily on the context it receives. In a RAG system, the retrieved information gives the LLM additional context that can help it produce a more useful answer.
This does not mean that RAG changes the model itself. Unlike fine-tuning, which updates a model through additional training, RAG usually works by adding relevant information to the model’s prompt at the time of the request.
This makes RAG a flexible approach for many business use cases. Organizations can update the underlying knowledge source without retraining the entire model.
For example, if a company updates its product documentation, a RAG system can retrieve the new information as soon as it has been added to the knowledge base or index.
RAG and vector databases
Many RAG systems use vector databases to store and retrieve information.
A vector database stores embeddings, which are numerical representations of text, images, audio, or other data. These embeddings help AI systems find information based on semantic similarity rather than exact keyword matches.
When a user asks a question, the query can be converted into an embedding. The system then compares that query embedding with stored document embeddings to find the most relevant passages.
This process is called vector search or similarity search.
Vector databases are useful in RAG because they allow systems to retrieve information that is conceptually related to a question, even when the wording is different.
For example, a user might ask, “How do I change my login details?” The system may retrieve a document titled “Resetting your account credentials” because the meaning is similar, even though the keywords are not identical.
RAG and LLM embeddings
LLM embeddings are a key part of many RAG workflows.
Embeddings convert text or other data into mathematical vectors that capture meaning and relationships. In RAG, embeddings are often used to represent both the user query and the source documents.
This allows the system to identify which pieces of information are most relevant to the user’s question.
High-quality embeddings can improve the relevance of retrieved content. Poor embeddings, incomplete source data, or badly structured documents can reduce the quality of the RAG output.
This is why data preparation, annotation, evaluation, and human review are important when building RAG systems.
A RAG system is only as strong as the information it can retrieve.
Use cases of Retrieval-Augmented Generation
Retrieval-Augmented Generation can be used across many AI and business applications.
Enterprise Knowledge Assistants
RAG can help employees search internal knowledge bases, policies, reports, and documentation using natural language. Instead of browsing through many files, users can ask a question and receive a summarized answer based on relevant internal sources.
Customer Support Chatbots
RAG can improve customer support automation by retrieving the latest support articles, product information, troubleshooting steps, or account guidance before generating an answer.
Search Relevance
RAG can improve search experiences by combining semantic retrieval with generated summaries. This helps users find relevant answers even when they do not know the exact search terms.
Legal and Compliance Research
RAG can support legal, compliance, and policy workflows by retrieving relevant clauses, guidelines, or regulations before generating a summary or answer. Human review remains important in these high-risk contexts.
Healthcare and Life Sciences
RAG can help retrieve medical literature, clinical documents, research summaries, or internal knowledge. Because healthcare is a high-stakes field, outputs should be carefully validated by qualified professionals.
Product Documentation
Companies can use RAG to build AI assistants that answer questions about products, APIs, manuals, and technical documentation.
Market Research and Customer Insights
RAG can help analyze survey responses, interview transcripts, support tickets, and customer feedback by retrieving relevant passages and summarizing patterns.
Training and Education
RAG can power learning assistants that retrieve relevant course materials, manuals, or knowledge base articles before answering student or employee questions.
Benefits of RAG
Retrieval-Augmented Generation offers several important benefits for AI systems and businesses.
More Accurate Answers
By grounding responses in retrieved information, RAG can help reduce unsupported or incorrect answers.
Access to Current Information
RAG allows AI systems to use updated external sources rather than relying only on the model’s training data.
Use of Company-Specific Knowledge
Businesses can connect LLMs to their own documents, policies, product information, and internal knowledge bases.
Reduced Need for Model Retraining
Organizations can update the knowledge source without retraining the entire language model.
Better Search and Discovery
RAG can improve the way users find information across large document collections, support portals, websites, and enterprise systems.
Improved Transparency
When implemented well, RAG systems can show which sources were used to generate an answer. This can improve trust and make outputs easier to verify.
Challenges of RAG
Although RAG is powerful, it also comes with challenges.
Data Quality
If the underlying source data is incomplete, outdated, duplicated, biased, or inaccurate, the RAG system may retrieve poor context and generate poor answers.
Retrieval Quality
The system must retrieve the right information at the right time. If retrieval fails, the model may receive irrelevant or misleading context.
Chunking Strategy
Documents are often split into smaller passages before indexing. If these chunks are too short, too long, or poorly structured, the system may lose important context.
Evaluation
RAG systems need careful evaluation. It is not enough to check whether the generated answer sounds good. Businesses must evaluate whether the retrieved information was relevant and whether the final answer was accurate.
Hallucination Risk
RAG can reduce hallucinations, but it does not eliminate them. The model may still misinterpret retrieved context, combine information incorrectly, or generate unsupported statements.
Security and Access Control
Enterprise RAG systems must respect permissions. Users should only retrieve and receive information they are authorized to access.
Maintenance
RAG systems need ongoing maintenance. Source documents, indexes, embeddings, retrieval settings, and evaluation benchmarks may need to be updated over time.
RAG in business
RAG is one of the most important techniques for bringing generative AI into business environments.
Many organizations want to use large language models, but they need those models to understand their own data. RAG helps bridge that gap by connecting generative AI with enterprise knowledge.
Common business applications include internal AI assistants, customer support automation, enterprise search, product documentation assistants, compliance research tools, sales enablement platforms, market research analysis, knowledge management systems, employee onboarding tools, and ecommerce search and recommendations.
For businesses, the value of RAG comes from making internal knowledge easier to access and use. It can help employees work faster, improve customer experiences, and reduce the time spent searching through large volumes of information.
RAG and data quality
Data quality is critical for successful RAG systems.
A RAG system depends on the information it retrieves. If the source data is poorly organized, incomplete, outdated, or inconsistent, the generated answers may also be unreliable.
Important data quality factors include accurate source documents, clear document structure, relevant metadata, clean formatting, up-to-date information, representative content, removal of duplicates, proper access controls, and evaluation by human experts.
High-quality data preparation can improve retrieval relevance and answer quality. Human evaluation can also help identify gaps, errors, and edge cases that automated systems may miss.
This is especially important for enterprise AI systems where users expect reliable and domain-specific answers.
Future of Retrieval-Augmented Generation
The future of RAG is closely connected to the growth of enterprise AI, agentic AI, multimodal AI, and domain-specific large language models.
As companies use generative AI in more business workflows, RAG will become increasingly important for connecting models to trusted knowledge sources. Future RAG systems are likely to become more advanced, combining text, images, audio, video, structured data, and real-time information.
RAG may also become more closely connected with agentic AI systems. In these workflows, AI agents may retrieve information, compare sources, perform tasks, and decide when additional context is needed.
Evaluation will become even more important. Businesses will need to measure not only whether an answer sounds fluent, but whether it is grounded, accurate, relevant, safe, and useful.
Conclusion
Retrieval-Augmented Generation is an AI framework that connects large language models with external knowledge sources before generating answers. It helps AI systems produce responses that are more relevant, current, and grounded in specific information.
RAG is especially valuable for businesses that want to use generative AI with their own data, including documents, policies, product information, customer support content, research, and internal knowledge bases.
By combining retrieval, embeddings, vector databases, and generative AI, RAG has become a foundational technique for enterprise AI applications. Its success depends on high-quality data, strong retrieval performance, careful evaluation, and responsible implementation.