In the context of training data for parsing legal documents, “AI contract analysis” refers to the use of machine learning models which are trained on large, annotated datasets of legal contracts in order to automatically identify and evaluate key information.
Manual contract review is resource-intensive and difficult to scale. With business-to-business involvement usually governed by contracts, in-house legal teams can spend up to half of their time just reading and reviewing contracts. An estimated 14-20% of developed countries’ GDP is linked to contract review. At the individual level, legal billing rates often range from $500–$900+ per contract (in markets like Australia and the USA), meaning that even routine reviews are costly, and more detailed analyses take even longer and cost even more.
Using AI in the legal domain is not new, with a dozen tools having been around for a decade or more. Legal AI vendors report that using AI for contract review can reduce the time spent on lower-complexity contracts by up to 75%.
It’s no surprise that AI contract analysis tools are gaining traction: done well, they can be a genuine game-changer for legal teams, accelerating turnaround times and freeing lawyers to focus on higher-value work.
But these tools need to be trained on the right data, fine-tuned by the right experts and have access to the right playbooks of prompts before they can live up to the promise of reducing costs and improving efficiency in contract analysis and contract review.
Training AI for contract review? LXT delivers expert-annotated contract data
for precision and scale.
From risk clauses to obligations and terminology, LXT helps models learn how legal language actually works.
What to look for in an AI contract review and analysis tool
Trained on relevant data
There are several critical factors that determine whether an AI contract review and analysis tool works as advertised. The first one is whether the system has been trained on legal language and legal reasoning, and fine-tuned by legal contract experts.
General-purpose language models can shorten documents, pulling out key facts, but they often miss issues that depend on context or jurisdiction. This includes risks related to non-compete clauses, termination provisions, employment conditions, payment terms, indemnity and breach-of-contract clauses, provisions for dispute resolution, vague or ambiguous wording, and so on, all of which can vary by region.
Access to the internal playbook
Legal firms typically have an internal “playbook”. This contains information and rules such as standard contract language, common counterparty objections, legal rationale for clauses, escalation thresholds, approved fallback clauses, etc.
Giving the AI access to this playbook allows it to perform the bulk of the standard work of contract analysis, reducing the effort required for the human legal review.
This is an area where “off-the-shelf” genAI is possibly worse than no AI at all. If the AI contract review tool does not reliably follow the same rules as the human contract reviewer, then the cognitive load of cross-checking the information against the company’s playbook falls to the human. So using an AI tool that does reliably follow the same rules as the human is critical.
Auditable trail of references
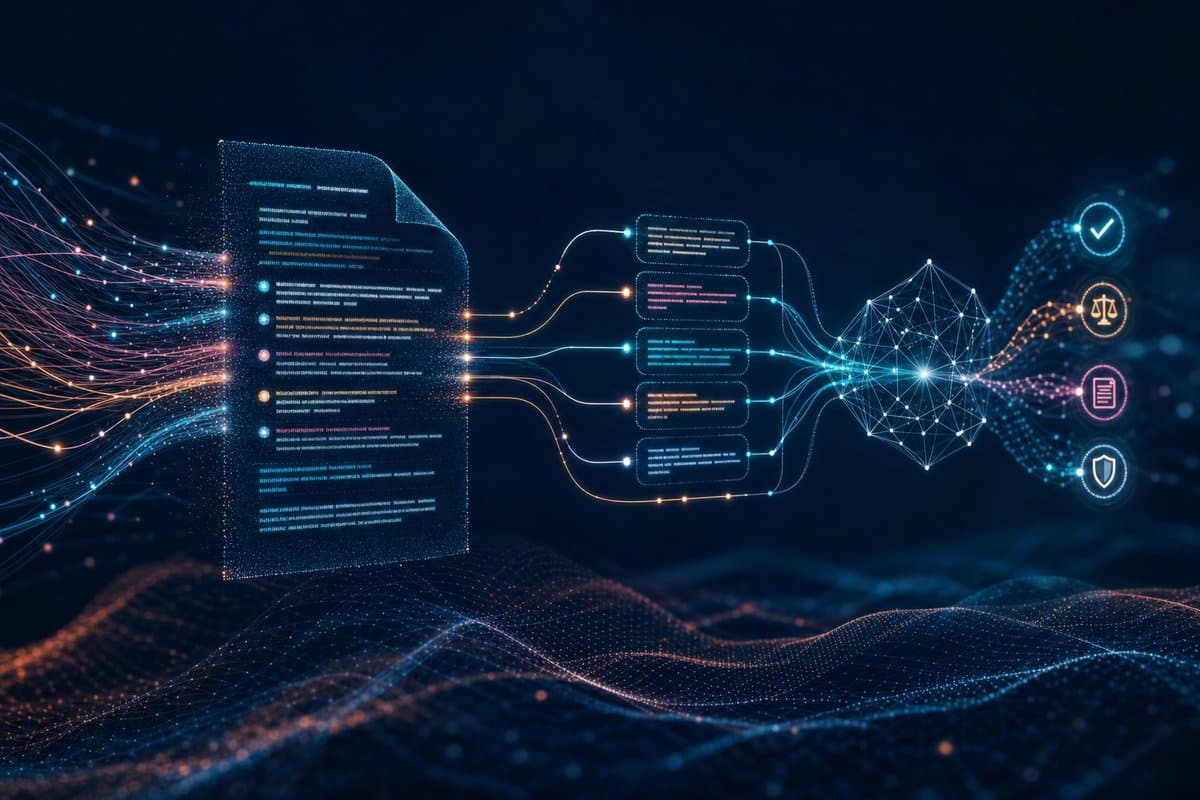
More effective systems break contracts into smaller components which are categorised and analysed both independently and in relation to each other. These systems output information in specific formats, containing text that can be traced back to specific sections of the document. This makes it easier to review and verify results.
Fit into existing workflows
Practically speaking, the AI contract review tool needs to slot into existing workflows for the least amount of disruption. Many legal teams work primarily in Microsoft Word, so tools that operate within that environment are easier to adopt. Features such as clause libraries and risk-flagging support existing workflows.
Security and accuracy
Finally, without a doubt, data security and accuracy are critical when dealing with sensitive agreements.
What improves performance
Stronger systems tend to use structured, multi-pronged approaches, rather than relying on a single model output.
One increasingly effective approach to the automatic review of legal contracts is the use of agents. Instead of asking one model to do everything, different components are made responsible for tracking specific aspects of the contract. One agent might identify where key information appears at the clause level. Another extracts parties and obligations. A third flags risks such as liability caps or termination provisions. This division of labour helps reduce omissions and can make the process more transparent.
This approach aligns with how legal review is often carried out in practice. As mentioned above, legal teams commonly rely on internal playbooks that guide reviewers through specific checks. In AI systems, these playbooks can be implemented as an agent following a sequence of targeted prompts, each focused on a particular issue. This leads to more consistent results and clearer reasoning.
Training data and training methods also influence performance. Reinforcement learning can be used to align model outputs with desired legal outcomes, such as correctly identifying a risk or classifying a clause. Missed issues are penalised and accurate issues rewarded, leading to improved accuracy in specific areas of interest to legal teams.
The quality and relevance of training data are equally important. Systems tend to perform better when they are trained on a firm’s own contracts, since these reflect actual negotiation patterns based on preferred clause structures and organisation-specific risk tolerances.
Datasets that include a range of contract types and jurisdictions are effective at improving a model’s accuracy, particularly when they have been annotated by legal experts. In contrast, models trained only on generic or templated documents are more likely to miss variation and edge cases.
A new danger to watch for
Like all tools based on LLMs, AI contract tools can provide confidently incorrect outputs, they can miss obligations, fail to flag liabilities or misinterpret how clauses interact. The factors listed above will generally counteract these inherent weaknesses.
A somewhat fascinating attribute of LLMs, that is often described under the umbrella of “emergent capability”, has recently entered the general conversation around AI. This is the fact that LLMs encode semantic patterns using syntactic patterns.
The strength of this pairing between syntax and semantics by LLMs is that generating tokens in the specific order that produces grammatical syntactic patterns also produces useful semantic patterns, which appears to us as sensible, reasoned responses to our prompt. An insidious weakness of this fact is that specific semantic outcomes can be encouraged simply by including particular syntactic phrasings.
This manipulation of the attention mechanism of LLMs for nefarious purposes has been called “”: it is a new category of risk in which “deliberately crafted legal language […] systematically distorts analysis performed by artificial intelligence without arousing the suspicion of the human reader”
These phrases can be then exploited in contracts, for example to predispose a language model to view a contract favourably by including an abundance of phrases that typically precede positive outcomes.
Yet again, the way to counter this new threat is by training models on carefully curated and annotated training data, using legal experts backed by LLM red-teaming experts to create fine-tuning data, and making sure the LLMs agents have mechanisms to deal with all known threats.
The bottom line
AI contract review and analysis do not succeed because of bigger models or better prompts alone. They succeed when structured workflows, domain-specific training and jurisdiction-specific legal data come together. They succeed when AI does the tedious grunt work, while humans are allowed to do what we do well, and to be supported in the things that are cognitively draining.
As adoption grows, the real competitive advantage won’t come from generic AI capabilities. Rather, it will come from systems built on the right data that fit into existing human workflows, and that reliably return decisions that match human judgement.